Cybersecurity of AI agents in financial services under EU law
Why behavioural monitoring is becoming a compliance requirement for AI agents under the AI Act, DORA, GDPR and the Cyber Resilience Act.
We handle your details as described in our privacy notice.
Five questions EU law expects you to answer after an AI agent incident
When an AI agent goes off script, the AI Act, DORA, the GDPR and the Cyber Resilience Act expect you to have answers. Five questions to test whether you would.
Henrik Nolte ·
What the OpenAI x Hugging Face incident reveals about detecting agent behavior at runtime
The OpenAI x Hugging Face incident shows how difficult it is to maintain visibility over autonomous agents once they are running.
Tim Van hamme ·
Beyond the lethal trifecta
The lethal trifecta has become the default model for reasoning about AI agent risk, but it only captures the confidentiality corner. As agents gain tools, integrity and availability risks demand a fuller model built on data flow.
Yusuf Hussein ·
The Meta AI security incident shows the risk of unauthorized agentic workflows
Attackers reportedly used Meta's AI support assistant to take over high-value Instagram accounts by combining legitimate capabilities into an unauthorized workflow. The broader lesson is that tool-calling AI agents introduce security risks at the workflow level.
Thomas Vissers ·
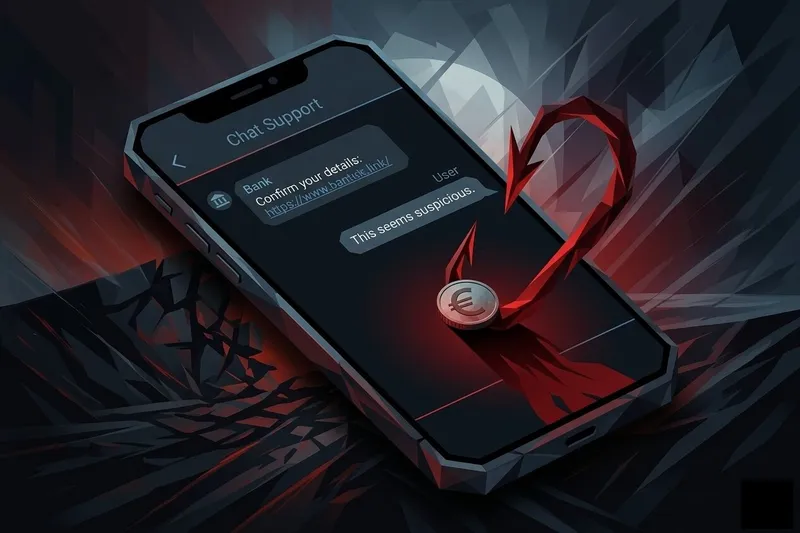
How we helped a leading European bank secure their financial AI assistant
Blue41 tested how a European banking AI assistant handled untrusted transaction data. The case shows why financial institutions need runtime visibility and layered controls when deploying AI assistants in banking.
Thomas Vissers & Tim Van hamme ·
Lessons from the Blue41 x OWASP workshop on breaking AI guardrails
Tim Van hamme ·
Inside the AI security conclave
At last week's invite-only Dagstuhl Seminar on LLM Security, Blue41 joined leading researchers from academia and industry in reaching a clear consensus: AI security must evolve beyond input-output filtering to systems-level defense.
Tim Van hamme ·
Why AI security must move beyond guardrails
Researchers from OpenAI, Anthropic, Google DeepMind, and ETH Zürich published a joint study with a sobering conclusion: the guardrails protecting today’s AI applications can be bypassed across the board.
Thomas Vissers ·
Jailbreaking: The Researcher's Playground
Jailbreaking: Not just a researcher's game. Discover why today's AI safety measures might be more fragile than you think.
Tim Van hamme ·
Unmasking Prompt Injection Attacks
This article explains what (indirect) prompt injection attacks are, how they differ from jailbreaks, and offer key strategies to secure LLM-powered systems.
Tim Van hamme ·
Real-world attacks on LLM applications
Attacks like prompt injections, indirect prompt injections, and the inherent issue of hallucinations are not just theoretical threats—they are being actively exploited and cause damage to businesses.
Thomas Vissers ·
Hallucinations: LLMs' major reliability problem
Despite the powerful capabilities of LLMs, enterprises face challenges when moving from prototypes to production-grade AI deployments. A key concern when exposing LLM-based systems to the real word is reliability, most notably exemplified by so-called hallucinations.
Thomas Vissers ·
LLMs: The Next Frontier in Cybersecurity?
This post delves into the intricacies of LLMs, exploring how they work and the vulnerabilities they present, especially when used in applications such as AI assistants.
Jo De Brabandere ·